<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="4.4.1">Jekyll</generator><link href="https://aeadataeditor.github.io/feed.xml" rel="self" type="application/atom+xml" /><link href="https://aeadataeditor.github.io/" rel="alternate" type="text/html" /><updated>2026-08-31T08:13:24-04:00</updated><id>https://aeadataeditor.github.io/feed.xml</id><title type="html">Office of the AEA Data Editor</title><subtitle>(current: Lars Vilhuber)</subtitle><author><name>AEA Data Editor</name></author><entry><title type="html">PSA: Please be precise when using Github as input to scientific articles.</title><link href="https://aeadataeditor.github.io/posts/2026-08-12-psa-github" rel="alternate" type="text/html" title="PSA: Please be precise when using Github as input to scientific articles." /><published>2026-08-12T00:00:00-04:00</published><updated>2026-08-12T00:00:00-04:00</updated><id>https://aeadataeditor.github.io/posts/PSA-Github</id><content type="html" xml:base="https://aeadataeditor.github.io/posts/2026-08-12-psa-github"><![CDATA[<p>If you use Github as an deposit for your scientific output, or you are re-using somebody else’s Github deposit, please be precise. I have some thoughts…</p>

<!-- more -->

<p>From a recent (draft) replication package:</p>

<blockquote>
  <p>Data on Kelly et al. (2021)’s patent indicator are downloaded from the authors’ GitHub repository. A copy of the data is provided as part of this archive. The data are in the public domain. To download, visit at https://github.com/KPSS2017, click the pinned repository named “Measuring-Technological-Innovation-Over-the-Long-Run-Extended-Data,” and download “PatentSimilarityImportanceBreakthrough_forPost2022.csv.zip”.</p>
</blockquote>

<p>A few things, first for those re-using the data, and then for those providing the data.</p>

<h2 id="for-re-users">For re-users</h2>

<h3 id="citing">Citing</h3>

<p>If using the Github data, and not the replication package to the original article, the Github data must be cited. Here, that would be</p>

<blockquote>
  <p>Kelly, B., Papanikolaou, D., Seru, A. and Taddy, M. 2023. <em>Updates and Extension of Measuring Technological Innovation Over the Long Run</em>. https://github.com/KPSS2017/Measuring-Technological-Innovation-Over-the-Long-Run-Extended-Data, version from November 2023.</p>
</blockquote>

<p>On the <a href="https://github.com/KPSS2017/Measuring-Technological-Innovation-Over-the-Long-Run-Extended-Data/blob/main/README.md">Github README</a>, the authors actually say</p>

<blockquote>
  <p>The version released on Sept 29, 2023 is the latest.</p>
</blockquote>

<p>but the <a href="https://github.com/KPSS2017/Measuring-Technological-Innovation-Over-the-Long-Run-Extended-Data/commits/main/">commits</a> on the Github actually tell a different story: there are September and November updates to the deposit. Whether those are materially different is not clear (these are ZIP files), but as a re-user, you should identify the version you ACTUALLY used.</p>

<p>Note that the authors ask that their published article be cited as a source. That is fine, as long as the re-user ALSO cites the actual source of the data, which is Github.</p>

<h3 id="downloading">Downloading</h3>

<p>The very verbose description is actually not the best way. First, the actual Github repository has a direct link. The <em>pinned</em> repositories can change over time, without any reason. Re-users should not rely on that. In fact, as I mentioned above, there are multiple commits. Unless the Github owners manipulate those commits (possible), the specific commit is what should be identified, possibly in the citation, but definitely in the download instructions. Here is the same verbose instructions expressed as a single URL:</p>

<blockquote>
  <p>Download
<a href="https://github.com/KPSS2017/Measuring-Technological-Innovation-Over-the-Long-Run-Extended-Data/blob/42f283517d72d90272f151867bb7b22744e23b2f/PatentSimilarityImportanceBreakthrough_forPost2022.csv.zip">https://github.com/KPSS2017/Measuring-Technological-Innovation-Over-the-Long-Run-Extended-Data/blob/42f283517d72d90272f151867bb7b22744e23b2f/PatentSimilarityImportanceBreakthrough_forPost2022.csv.zip</a></p>
</blockquote>

<p>which preserves the metadata (it doesn’t directly download the data, but rather, allows you to see the context in which you are downloading the data). Much simpler.</p>

<h3 id="distributing">Distributing</h3>

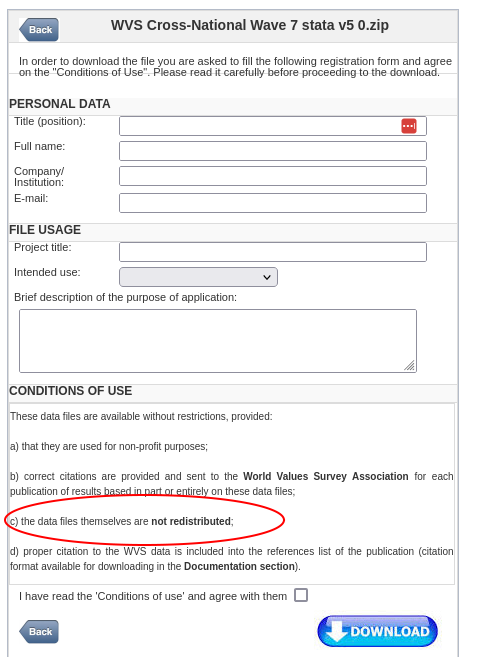
<p>The quote I provided mentions “data are in the public domain.” That is incorrect. The data are downloadable by anybody without registration. However, “public domain”  is a legal term that means that nobody has the copyright on the data. Possibly because the entity producing the data is legally excluded from claiming copyright (oversimplifying somewhat, in the US, the federal government), or because the person producing the data has explicitly relinquished this (often under a “CC0”  license).</p>

<p>But in the absence of true “public domain”, the data are copyrighted by the original authors. Fair-use is fine (so using the data is likely the intent of posting it on the internet here), but re-purposing the data may not be. Copyright = all rights reserved does not need an explicit mention! So strictly speaking, you need the authors’ permission to redistribute the data, or you might have to claim “fair use” explicitly. We usually send the re-users to ask permission, which is cleaner.</p>

<h2 id="for-authors">For authors</h2>

<p>All of the above can be greatly simplified if authors (those posting on Github) followed some simple best practices:</p>

<h3 id="define-a-license">Define a license</h3>

<p>Authors should clearly specify the license under which the data are released. Common licenses include Creative Commons (CC) licenses, which allow for various levels of reuse of data, or open-source software licenses like MIT or GPL, which might be more relevant for code. A dual-license setup can work. See <a href="https://aeadataeditor.github.io/aea-de-guidance/Licensing_guidance">guidance</a> on my website. The license should be expressed as a <code class="language-plaintext highlighter-rouge">LICENSE.txt</code> or <code class="language-plaintext highlighter-rouge">LICENSE.md</code> file in the root of the repository, it will be picked up and displayed in the sidebar by Github.</p>

<p>If authors do NOT want to provide a general license, that is also fine, but they should likely explicitly say it, to be clear, although that may not be legally required: “Copyright John Doe and Alice Smith, all rights reserved. Permission to redistribute or reuse this data must be obtained from the authors.”</p>

<h3 id="versioning">Versioning</h3>

<p>Rather than having re-users guess at versions, and have long commit-based URLs, create tags or releases. Very easy to do in both <code class="language-plaintext highlighter-rouge">git</code>  and on Github. That would allow for much simpler URLs:</p>

<blockquote>
  <p>Download <a href="https://github.com/KPSS2017/Measuring-Technological-Innovation-Over-the-Long-Run-Extended-Data/blob/v1.1/PatentSimilarityImportanceBreakthrough_forPost2022.csv.zip">https://github.com/KPSS2017/Measuring-Technological-Innovation-Over-the-Long-Run-Extended-Data/blob/ <strong>v1.1</strong> /PatentSimilarityImportanceBreakthrough_forPost2022.csv.zip</a></p>
</blockquote>

<p>(OK, that’s not much shorter in this case, because of the long repository and file names, but it is easier to read).</p>

<h3 id="citation">Citation</h3>

<p>Authors in general prefer that you cite the article, because under current academic norms (at least in economics), is the only thing that counts. Nevertheless, if the article is published in 2021, and the data in 2023, re-users are misleading their readers because they materially reference data that does not exist at the cited location (the article, or its replication package), and cannot be easily linked. The solution is to cite both.</p>

<p>And to make that easy, use the <a href="https://docs.github.com/en/repositories/managing-your-repositorys-settings-and-features/customizing-your-repository/about-citation-files">CITATION.cff</a> file. It, too, is highlighted by Github in the right panel.</p>

<h3 id="preserving">Preserving</h3>

<p>And finally, if you have license and citation all tidied up, why not preserve it, and get a DOI to boot? This does away with the fragility of deposits and commits (anybody can delete their Github repo forever, in 30 seconds flat), and simplifies citation as well. You can do so nearly automatically (if creating releases) <a href="https://docs.github.com/en/repositories/archiving-a-github-repository/referencing-and-citing-content">via Zenodo</a>, or to <a href="https://github.com/marketplace/actions/dataverse-uploader-action">Dataverse</a>.</p>

<p>Re-users can then simply use the Zenodo version, which has a DOI, and is guaranteed to be preserved.</p>]]></content><author><name>AEA Data Editor</name></author><category term="dataeditor" /><category term="data editor tips" /><category term="reproducibility" /><category term="data citation" /><category term="Github" /><category term="licenses" /><summary type="html"><![CDATA[If you use Github as an deposit for your scientific output, or you are re-using somebody else’s Github deposit, please be precise. I have some thoughts…]]></summary></entry><entry><title type="html">The Same Code, a Different Answer: Stata Convergence Across Platforms</title><link href="https://aeadataeditor.github.io/posts/2026-07-24-stata-convergence-across-platforms" rel="alternate" type="text/html" title="The Same Code, a Different Answer: Stata Convergence Across Platforms" /><published>2026-07-24T00:00:00-04:00</published><updated>2026-07-24T00:00:00-04:00</updated><id>https://aeadataeditor.github.io/posts/stata-convergence-across-platforms</id><content type="html" xml:base="https://aeadataeditor.github.io/posts/2026-07-24-stata-convergence-across-platforms"><![CDATA[<p>A recent replication came to a halt on a first-stage regression. The authors’ code ran fine on the authors’ computer. It failed on ours. Same code, same data, same software package — different answer. Here is what it took to find out why, and some thoughts (lessons?).</p>

<!-- more -->

<h2 id="first-do-not-hide-the-output">First: do not hide the output!</h2>

<p>The immediate problem was not the regression itself. It was that we could not see the regression output, and thus the error.</p>

<p>The offending line was, in essence:</p>

<div class="language-stata highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">quietly</span><span class="w"> </span><span class="n">do</span><span class="w"> </span><span class="n">regression_55</span><span class="o">.</span><span class="n">do</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">quietly</code> suppressed exactly the output that would have explained the failure. The code simply stopped completing, with nothing on screen to say why. Diagnosing it meant unwinding the suppression before we could even start on the econometrics.</p>

<h2 id="its-not-exactly-the-code">It’s not exactly the code</h2>

<p>After some back and forth, the authors provided (credible) evidence that the code did run on their system. So we reduced their several hundred lines to a minimal working example of about two dozen, and sent it to Stata support, who responded promptly!</p>

<h2 id="it-is-not-the-operating-system">It is not the operating system</h2>

<p>Our first hypothesis was the obvious one. We had run on Windows Server (StataNow 19) and Linux (StataNow 19); the authors had run on Windows Enterprise (Stata 19). Operating system, then. Or version.</p>

<p>That was not enough. Stata’s technical staff ran the example across their internal collection of hardware and software, and reported:</p>

<blockquote>
  <p>convergence on Windows box running Stata 18 MP32 and Stata 19 MP8, but <code class="language-plaintext highlighter-rouge">set processors</code> to any number less than 8 cause not converging….Mac mini Apple M2 pro/ S19MP16 NOT…Linux/S19MP16, S19SE, S18MP2, S17MP2, S16MP2, NOT converged for any number of processors</p>
</blockquote>

<p>One should take particular note of this fact: On the <em>same</em> Windows machine, with the <em>same</em> Stata, the model converges or does not converge depending on how many processors you let it use. The authors, it turned out, had run Stata 19 MP10 — one of the <strong>few</strong> combinations in which the model converged at all.</p>

<p>The determining variable was not the operating system, and not the Stata version. It was the number of processors.</p>

<h2 id="what-was-actually-wrong">What was actually wrong</h2>

<p>Stata’s statisticians examined the code and the data, and the answer is that it’s not “a bug.” Mostly. Quoting from their reply:</p>

<blockquote>
  <p>Stata, like any other software package, has fixed criteria to convergence declaration. It’s not foolproof. There will be always cases where convergence will be “declared” and it shouldn’t.</p>
</blockquote>

<blockquote>
  <p>This is why we insist on the importance of examining the output and make sure that it makes sense. I looked at the output it shows several problems.</p>
</blockquote>

<p>Three symptoms, all visible in the output that <code class="language-plaintext highlighter-rouge">quietly</code> had been hiding:</p>

<blockquote>
  <p>1) there are missing standard errors. … an indication that there is a problem with the Hessian (either it has missing values, or for some reason it can’t be inverted), so you can’t trust your results.</p>

  <p>2) There are huge confidence intervals,… coefficients are poorly identified.”
3) The problem is the matrix of second derivatives, that
is non invertible. In the cases where we get ‘convergence’,
we get huge or missing standard errors, meaning that it can’t really be inverted.”</p>
</blockquote>

<p>The mechanism is worth spelling out, because it explains the platform sensitivity. Stata declares convergence when the scaled gradient satisfies <code class="language-plaintext highlighter-rouge">g*inv(H)*g' &lt; nrtolerance()</code>, with a default of <code class="language-plaintext highlighter-rouge">1e-5</code>. That criterion <em>requires inverting the Hessian</em>. When the Hessian is numerically singular, the criterion cannot be evaluated in a meaningful way — and whether it happens to be evaluated as satisfied comes down to floating-point details that differ with the number of processors, the BLAS in use, and the order in which sums are accumulated (my words, not theirs).</p>

<p>They continued.</p>

<blockquote>
  <p>On Mac, I don’t get convergence by default, but I get it if I disable the <code class="language-plaintext highlighter-rouge">nrtolerance</code>, meaning that this is the tolerance that the model fails to meet.</p>
</blockquote>

<blockquote>
  <p>If I write <code class="language-plaintext highlighter-rouge">shownrtol</code> option instead, I will see that (the “minimum” of all tolerances) is 0, but exact zero means that something can’t be computed, in this case the nrtol (which requires inverting the Hessian).</p>
</blockquote>

<p>So the model was not identified on any platform. On most configurations Stata correctly refused to declare victory. On a few — including the authors’ — it declared convergence it should not have.</p>

<h2 id="why-this-matters-beyond-one-paper">Why this matters beyond one paper</h2>

<p>Two observations:</p>

<p>This was one regression out of many dozens in the paper. The rest converged. <em>How well</em> they converged we did not investigate — that remains for the authors, and for future replicators.</p>

<p>More importantly, consider what would have happened had our replication machines been configured slightly differently. <strong>We only detect some of these issues.</strong> If we happen to land on the same sweet-spot hardware and software configuration as the authors, we never see a discrepancy, and the paper passes. The non-identification is still there; we just never trip over it. And it is genuinely hard for authors to diagnose on their own, unless they happen to maintain the same museum of hardware and software versions that Stata does.</p>

<h2 id="lessons">Lessons</h2>

<p>I will not pronounce on the econometrics — that is the authors’ problem, and for future replicators (who have a reproducible package to work with!) But two things are general:</p>

<p><strong>Know your regressions.</strong> Missing standard errors and implausibly wide confidence intervals are not cosmetic blemishes to be tidied up in the table. They are the software telling you the model is not identified. Look at the output.</p>

<p><strong>Do not suppress your output.</strong> In Stata, that means thinking twice about <code class="language-plaintext highlighter-rouge">quietly</code>. The equivalents elsewhere are just as effective at hiding a problem: <code class="language-plaintext highlighter-rouge">source()</code> without <code class="language-plaintext highlighter-rouge">echo=TRUE</code> in R, or a stray <code class="language-plaintext highlighter-rouge">;</code> in MATLAB. Silence during a long run feels tidy. It is not tidy — it is a diagnostic you have thrown away, and you will want it back at precisely the moment it is gone.</p>

<p>Thanks to <a href="https://bsky.app/profile/stata.bsky.social">@stata.bsky.social</a>, whose helpdesk responded quickly and then very thoroughly, and did a fantastic job diagnosing this.</p>

<p>Good night, and good computing!</p>

<hr />

<p><em>This post is adapted from <a href="https://bsky.app/profile/aeadata.bsky.social/post/3mreaq7ll4k2v">a thread</a> originally posted on Bluesky.</em></p>]]></content><author><name>AEA Data Editor</name></author><category term="dataeditor" /><category term="data editor tips" /><category term="reproducibility" /><category term="replication packages" /><category term="Stata" /><category term="Code" /><summary type="html"><![CDATA[A recent replication came to a halt on a first-stage regression. The authors’ code ran fine on the authors’ computer. It failed on ours. Same code, same data, same software package — different answer. Here is what it took to find out why, and some thoughts (lessons?).]]></summary></entry><entry><title type="html">What to do when you have private, even anonymous data as part of your analysis?</title><link href="https://aeadataeditor.github.io/posts/2026-05-08-private-data" rel="alternate" type="text/html" title="What to do when you have private, even anonymous data as part of your analysis?" /><published>2026-05-08T00:00:00-04:00</published><updated>2026-05-08T00:00:00-04:00</updated><id>https://aeadataeditor.github.io/posts/private-data</id><content type="html" xml:base="https://aeadataeditor.github.io/posts/2026-05-08-private-data"><![CDATA[<p>In economics, it is not uncommon to have data that are so private that the provider cannot be named. Firms (because usually these are firms) may be unwilling to reveal themselves in the analysis. Sometimes, this also applies to locations, when revealing the location might reveal sensitive information, or might compromise a follow-up study.</p>

<p>Of course, it is the first claim a fraudster would make, too. So how can we help legitimate authors separate themselves from the fraudsters, and still publish interesting and <strong>real</strong> research in journals?<sup id="fnref:updated"><a href="#fn:updated" class="footnote" rel="footnote" role="doc-noteref">1</a></sup></p>

<!-- more -->

<h2 id="the-aeas-policy-on-private-data">The AEA’s policy on private data</h2>

<p>The <a href="https://www.aeaweb.org/journals/data/data-code-policy">AEA Data and Code Availability Policy</a> asks that authors provide access to all data used in a published paper. But it also acknowledges that there may be cases where data cannot be shared.</p>

<blockquote>
  <p>In rare cases where any of requirements (i)-(iv) above cannot be met due to valid constraints beyond the authors’ control, the AEA data editor and the journal editor may choose to modify the requirement(s), and such modifications will be noted in the article acknowledgements. However, in these cases the source of the data must still be disclosed to the AEA data editor prior to final acceptance of the paper.</p>
</blockquote>

<h2 id="how-often-does-this-happen">How often does this happen?</h2>

<p>A legitimate question is: does this happen often? The answer is no. Upon ingest, data access is classified into five categories: included (fully open data), and four categories of restricted access, going from “very easy to access” to “very difficult”.<sup id="fnref:dcaf"><a href="#fn:dcaf" class="footnote" rel="footnote" role="doc-noteref">2</a></sup></p>

<p><img src="/images/figure_access_provision.png" alt="Data access classification" /></p>

<p>The “anonymous data” obviously falls into the last category, and in the last twelve months, we’ve had 5 such cases.</p>

<h2 id="what-do-we-then-do">What do we then do?</h2>

<h3 id="data-provision">Data provision</h3>

<p>In a nutshell, our first preference is that authors are allowed to share the data with us, but not-for-publication. This means that we will have access to the data, and can run code against the data, but won’t publish the data.<sup id="fnref:nopub"><a href="#fn:nopub" class="footnote" rel="footnote" role="doc-noteref">3</a></sup></p>

<p>We provide a secure upload link, different from the draft deposit. Readers can view our template email with which we reach out to authors at <a href="https://aeadataeditor.github.io/LDI-Research-Aide/docs/emails/Request-Restricted-Access-Data.html">here</a>. Of course, authors should check with their data provider if provision of data is OK. We can also sign a non-disclosure agreement (NDA) if necessary (referenced in the email), but we stand by our word, and most authors take us up on that.</p>

<h3 id="name-of-the-provider">Name of the provider</h3>

<p>For the name of the company, we may sign a separate NDA, to protect both us and the authors. Again, we have an SOP (Standard Operating Procedure) for that; here’s the (separate) <a href="https://aeadataeditor.github.io/LDI-Research-Aide/docs/emails/Request-Unknown-Provider-Info.html">template email</a> for that. Important: the data provider should be aware of us signing the NDA, as we will publish the fact that the authors revealed the name to me.</p>

<h3 id="verification">Verification</h3>

<p>Usually, I then contact the data provider, or a representative of the provider, directly. I keep no records of identity or other means of contact, and usually make video or phone calls, possibly using WhatsApp or Signal. I validate the representative’s identity through independent means (are they really who they claim to be). I ask questions regarding the authors’ access to the data: Did they actually get access? How? Can others get access? Why is the provider’s identity meant to be secret?</p>

<p>Once I have satisfied my professional curiosity, I report back to the editor in charge of the paper, and convey my opinion regarding the legitimacy of the data provider and of the data. The editor then makes a decision on whether to proceed with publication. Once we have obtained the data, we proceed to verify computational reproducibility. We will also work with the authors to make the restrictions and possibilities clear in the README.</p>

<h3 id="publication">Publication</h3>

<p>Once all the other pieces fall into place, and the article is published, readers can find this information (for now) in the title page footnote:</p>

<blockquote>
  <p>“As part of the reproducibility checks conducted by the AEA, the identity of the anonymous data provider was revealed to the Data Editor, who verified legitimacy of the data use agreement and of access to the data.”</p>
</blockquote>

<p>An example (albeit membership-gated) is</p>

<blockquote>
  <p>Haegele, Ingrid. 2026. “Talent Hoarding in Organizations.” American Economic Review 116 (8): 3110–51. <a href="https://doi.org/10.1257/aer.20220264">https://doi.org/10.1257/aer.20220264</a></p>
</blockquote>

<p><img src="/images/Screenshot-private-aer.20220264.png" alt="Screenshot of the title page footnote" /></p>

<h2 id="closing-remarks">Closing remarks</h2>

<p>Our process is not perfect, and probably there are ways to game it. We don’t reveal all the checks that we do, which may also include checking the data content, and for consistency with public data. But we hope that this allows the readers to have some confidence in the research being presented. The authors, of course, should also be sure to write their publication in such a way that it can be replicated in other contexts. After all, their access to a single anonymous firm, city, municipality, etc. remains a “N of 1” case, very interesting, but in need of generalization. The paper and the replication package hopefully help with that.</p>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:updated">
      <p>This post was updated on 2026-08-18 with an example article. <a href="#fnref:updated" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:dcaf">
      <p>The first pass at this is made by authors self-classifying their data, on the <a href="https://www.aeaweb.org/journals/forms/data-code-availability">Data and Code Availability Form</a>. We may revisit this once we’ve seen the replication package, and will recode this in our internal database. <a href="#fnref:dcaf" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:nopub">
      <p>To be clear, <strong>we</strong> actually never publish data or code regardless of when or how authors have provided it. The authors publish their data and their code, but in a space that we make available. We never touch their draft deposits, only review them, and we certainly never add anything to it. In some rare cases, we may help the authors by removing files that should not be there (obvious junk files). <a href="#fnref:nopub" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>AEA Data Editor</name></author><category term="data editor tips" /><category term="replication packages" /><category term="terms of use" /><category term="private data" /><summary type="html"><![CDATA[In economics, it is not uncommon to have data that are so private that the provider cannot be named. Firms (because usually these are firms) may be unwilling to reveal themselves in the analysis. Sometimes, this also applies to locations, when revealing the location might reveal sensitive information, or might compromise a follow-up study. Of course, it is the first claim a fraudster would make, too. So how can we help legitimate authors separate themselves from the fraudsters, and still publish interesting and real research in journals?1 This post was updated on 2026-08-18 with an example article. &#8617;]]></summary></entry><entry><title type="html">What to do when PII is detected in a replication package?</title><link href="https://aeadataeditor.github.io/posts/2026-05-05-pii" rel="alternate" type="text/html" title="What to do when PII is detected in a replication package?" /><published>2026-05-05T00:00:00-04:00</published><updated>2026-05-05T00:00:00-04:00</updated><id>https://aeadataeditor.github.io/posts/pii</id><content type="html" xml:base="https://aeadataeditor.github.io/posts/2026-05-05-pii"><![CDATA[<p>I had previously described a very similar scenario in a <a href="2024-11-01-psid-requests">blog post about the PSID</a>, but I thought it would be useful to write a more general post about what to do when personally identifiable information (PII) is detected in a replication package. This reprises a lot of the same tasks as the earlier post.</p>

<!-- more -->

<p>The <a href="https://www.aeaweb.org/journals/data/data-code-policy">AEA Data and Code Availability Policy</a> asks that authors provide access to all data used in a published paper. But it also acknowledges that there are cases where data cannot be shared. This may be due to privacy concerns, proprietary rights to the data that are not the author’s, or terms of use that prohibit the sharing, redistribution, or publication of data.</p>

<p>In principle, Personally Identifiable Information (PII) should never be included in replication packages. There are multiple checks for this. Since the start of creating reports, we would (manually, or semi-automatically) run PII checks (based on <a href="https://github.com/J-PAL/stata_PII_scan">J-PAL’s PII_stata_scan.do</a>, and the replicator would add notes on that. More recent reports (since 2024) persistently include text alerting authors to check their data, regardless of the outcome of the check. When depositing data, authors are required to assert that <a href="https://aeadataeditor.github.io/aea-de-guidance/data-deposit-aea.html#can-individuals-be-identified">individuals cannot be identified</a>.</p>

<p>But… <strong>it happens</strong>. Authors believe that their team has removed all PII, and yet some leaks in. Sometimes, it’s because they forgot to remove the verbatim answer to “who takes care of your child when you are at work”. Sometimes, it’s the IP address of the respondent.</p>

<p>So what happens when an author inadvertently does share such data, and now needs to remove it? As a reminder, the author is committed (by <a href="https://www.aeaweb.org/journals/forms/data-code-archive-agreement">signing an agreement</a>) to not withdrawing the replication package. How to proceed? Read on!</p>

<h2 id="in-a-nutshell">In a nutshell</h2>

<p>The gist of the solution is the following, for AEA publications.</p>

<ul>
  <li>The author requests that the deposit (in the AEA case, ICPSR) <strong>unpublish</strong> the original replication package (call it V1) (also called “de-accessioning”), i.e., remove the ability to download the package. The journal (data editor, me) should be notified at the same time.</li>
  <li>Remove the infringing data from V1 of the replication package.</li>
  <li>[Ideally] Create a new, separate deposit that is compliant with IRB restrictions on PII. I expand on this below.</li>
  <li>Document the new location of the now absent data in the README of the replication package, and how somebody can access it.</li>
  <li>Revise your V1 replication package to take into account changed location, or coding of variables, as per our <a href="https://www.aeaweb.org/journals/data/revisions-policy">Policy on Revisions of Data and Code Deposits in the AEA Data and Code Repository</a>.</li>
  <li>Submit the revised replication package to the journal.</li>
  <li>The <strong>journal</strong> publishes V2 of the replication package, which is now compliant.</li>
</ul>

<p>Important notes:</p>

<ul>
  <li>At no time should any code be removed from the package. If at all, minimal changes should be made.</li>
  <li>It is never acceptable to simply remove the old package, without handling replacement.</li>
</ul>

<h3 id="preliminary-steps">Preliminary steps</h3>

<p>The first steps involve getting access to your own replication package. This may differ by when the replication package was published.<sup id="fnref:2"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">1</a></sup></p>

<ul>
  <li>For authors with papers published before 2019 (approximately)
    <ul>
      <li>All authors will need to get an openICPSR login, which will serve them both for the changes to the AEA and for creating the new PSID deposit.</li>
      <li>They will need to request access to the deposit. The <a href="https://www.openicpsr.org/openicpsr/contactUs">openICPSR helpdesk</a> may be able to help with that. The authors should mention the URL or DOI, and the openICPSR login they want the deposit associated with.</li>
    </ul>
  </li>
  <li>
    <p>For authors with more recent papers:</p>

    <ul>
      <li>They will need to re-create an ICPSR account <strong>with the same email as previously used</strong> since <a href="https://researcherpassport.icpsr.umich.edu/help">ICPSR changed their login system in Feb 2024</a>. The <a href="https://www.openicpsr.org/openicpsr/contactUs">openICPSR helpdesk</a> may help with that.</li>
      <li>They need to then <a href="https://www.aeaweb.org/journals/data/revisions-policy#createnewversion">create a new version</a>.</li>
    </ul>
  </li>
</ul>

<p><img src="/images/icpsr-create-new-version.png" alt="Create a new version" />]</p>

<h3 id="rules-that-apply-to-revisions-of-replication-packages">Rules that apply to revisions of replication packages</h3>

<p>Here are a few simple rules:</p>

<ul>
  <li>The modified package should differ only as necessary from the original package. Less work for the author, greater clarity for replicators, everybody wins.</li>
  <li>Journal-specific policies may apply. For instance, the AEA has a <a href="https://www.aeaweb.org/journals/data/revisions-policy">Policy on Revisions of Data and Code Deposits in the AEA Data and Code Repository</a>. Among other things, it requires that all changes be clearly identified.</li>
</ul>

<h3 id="fixing-the-problem-where-to-put-the-data">Fixing the problem: where to put the data?</h3>

<p>Once the preliminaries are done, here’s what authors need to do to remain compliant with AEA policy (similar rules may apply at other journals):</p>

<ul>
  <li>Consider how to preserve the PII-laden data.</li>
</ul>

<p>Ideally, you already have a copy of the data, to be compliant with AEA policy (5 years post-publication). There are options for preserving the data at your institution, or archives like ICPSR, but they vary over time. Talk to your data librarian, or to data custodians at ICPSR. Talk to the Data Editor.</p>

<ul>
  <li>The AEA prefers strongly that such deposits NOT require the authors’ consent to access.</li>
</ul>

<p>Rather, access should be granted based on clear terms of use (“provide IRB approval”), vetted by individuals not connected to the author, and likely to be present long after the author has retired. Institutions, like your own university or ICPSR, are ideal.</p>

<h3 id="fixing-the-problem-what-data-to-include">Fixing the problem: what data to include?</h3>

<p>If the variables that contain PII are not essential to the replication of the paper, then they can simply be removed from the replication package. This must still be documented!</p>

<p>If however, they are important to the analysis (left-hand side or right-hand side), you will need to be more creative. You may document that certain analyses are no longer feasible without the PII-laden, but should ensure that the code continues to run for all other analyses (for instance, because the PII-laden variables only affect one out of a gazillion robustness checks).</p>

<p>You may also be able to recode the PII, replacing them with innocuous but still unique identifiers. Finally, you may need to replace variables with fake or synthetic data, which will ensure the code runs, but may not produce the right results. Again, very important that this is documented in the README!</p>

<h4 id="back-in-the-aea-deposit">Back in the AEA deposit</h4>

<ul>
  <li>Log on to the V1 deposit. You should be in “Modifying” mode.</li>
  <li>Remove (delete) the PII data (<code class="language-plaintext highlighter-rouge">my_survey_1.dta</code>)</li>
  <li>Update the README with “PII-laden data for this package can be obtained from ICPSR upon provision of an IRB approval.” in an appropriate location. The ideal README follows the <a href="https://doi.org/10.5281/zenodo.7293838">Template README published by the Social Science Data Editors</a>, but make only minimal changes to the README in this deposit.
    <ul>
      <li>Delete the old README (<em>completely</em>),</li>
      <li>Upload the new README (in PDF format) to the same location the original one was</li>
    </ul>
  </li>
  <li><a href="https://www.aeaweb.org/journals/data/revisions-policy#identifying">Create a <code class="language-plaintext highlighter-rouge">CHANGES.txt</code>.</a>  Identify changes made. E.g. “V2: Removed PII-laden data, adjusted code.”.  It should look something like this:</li>
</ul>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>V1: Original deposit
V2: Removed PII-laden data, adjusted code.
</code></pre></div></div>

<ul>
  <li>Upload the <code class="language-plaintext highlighter-rouge">CHANGES.txt</code>.</li>
  <li>(If possible) Link to the DOI of the PII-laden deposit in the “Related publications” section of the deposit (use the <code class="language-plaintext highlighter-rouge">Import from DOI</code> functionality, choose <code class="language-plaintext highlighter-rouge">is supplemented by</code> for the <code class="language-plaintext highlighter-rouge">Relationship</code> field)</li>
  <li>You <em>may</em> have to add the “manuscript number” to the metadata, see <a href="https://aeadataeditor.github.io/aea-de-guidance/data-deposit-aea.html#scope-of-project-section">this link</a>. Use the last part of the DOI of the paper, e.g. if the paper DOI is <code class="language-plaintext highlighter-rouge">https://doi.org/10.1257/aer.p20161120</code> then the “manuscript number” should be <code class="language-plaintext highlighter-rouge">aer.p20161120</code>.</li>
  <li><a href="https://aeadataeditor.github.io/aea-de-guidance/data-deposit-aea.html#submitting-to-the-data-editor">Re-Submit to the AEA</a></li>
</ul>

<p><img src="/images/project-submit.png" alt="(Re-)Submit to the AEA" /></p>

<h2 id="the-end-state">The end state</h2>

<p>After all the fixes,</p>

<ul>
  <li>V1 is still visible, but can no longer be downloaded.</li>
</ul>

<p><img src="/images/openICPSR-study-unpublished.png" alt="Unpublished deposit shows banner" /></p>

<ul>
  <li>V2 is published, contains no PII data, (possibly) links to the deposit of the restricted data, and remains otherwise available to replicators. You are still in compliance with the AEA publication agreements and your obligations as an AEA author!</li>
</ul>

<h2 id="final-comments">Final comments</h2>

<p>Authors should feel free to reach out to their journal’s data and reproducibility editor with questions about the available options.</p>
<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:2">
      <p>The dividing line is approximately Oct 1, 2019. In 2019, <a href="https://aeadataeditor.github.io/aea-supplement-migration/programs/aea201910-migration.html">we migrated approximately 2,500 older replication packages into openICPSR</a>. Authors were not involved in this process, and so do not have operational access to the replication package. They do, however, have ownership of the deposit, and can request access to it. <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>AEA Data Editor</name></author><category term="data editor tips" /><category term="replication packages" /><category term="terms of use" /><category term="PII" /><summary type="html"><![CDATA[I had previously described a very similar scenario in a blog post about the PSID, but I thought it would be useful to write a more general post about what to do when personally identifiable information (PII) is detected in a replication package. This reprises a lot of the same tasks as the earlier post.]]></summary></entry><entry><title type="html">Preparing Replication Packages for 2026 AEA Papers and Proceedings</title><link href="https://aeadataeditor.github.io/posts/2026-01-19-preparing-pandp-replication-packages" rel="alternate" type="text/html" title="Preparing Replication Packages for 2026 AEA Papers and Proceedings" /><published>2026-01-19T00:00:00-05:00</published><updated>2026-01-19T00:00:00-05:00</updated><id>https://aeadataeditor.github.io/posts/preparing-pandp-replication-packages</id><content type="html" xml:base="https://aeadataeditor.github.io/posts/2026-01-19-preparing-pandp-replication-packages"><![CDATA[<p>For authors preparing the replication packages that accompany their 2026 AEA Papers and Proceedings publication <a href="https://www.aeaweb.org/journals/pandp">www.aeaweb.org/journals/pandp</a>: Here are some notes on preparing your replication package.</p>

<!-- more -->

<p><img src="/images/posts/2026/pandp-2026-prep.jpg" alt="Papers and Proceedings preparation checklist" /></p>

<p>Much of the preparation for papers published in Papers and Proceedings is the same as for the AEA journals, see <a href="https://aeadataeditor.github.io/aea-de-guidance/preparing-for-data-deposit.html">Step 1 for basic preparation</a> &amp; <a href="https://aeadataeditor.github.io/aea-de-guidance/data-deposit-aea.html">Step 2 if depositing at the AEA Data and Code repository</a>.</p>

<p>However, our compliance check is more limited than the checks conducted for peer-reviewed papers. Your replication package must nevertheless be fully compliant with the <a href="https://www.aeaweb.org/journals/data/data-code-policy">AEA Data and Code Availability Policy</a>.</p>

<p>This means: Should a reader or user of your replication package find errors or omissions at a later stage, you will be asked to remedy the situation in line with our <a href="https://www.aeaweb.org/journals/data/policy-revisions">Policy on Revisions of Data and Code Deposits</a>.</p>

<h2 id="what-do-we-do">What do we do?</h2>

<p>My replicators will review the deposit, review the README, and send you a filled-out checklist, verifying compliance with each item. If you want to get a perfect score (gamification!) you can find a <a href="https://aeadataeditor.github.io/assets/pdfs/aea-de-pre-publication-verification-form.pdf">printable checklist here</a>.</p>

<h2 id="repository-choices">Repository choices</h2>

<p>The use of the <a href="https://www.openicpsr.org/openicpsr/aea">AEA Data &amp; Code Repository</a> is strongly encouraged. Other repositories and archives considered to be “trusted” may be acceptable - if you ALREADY have a replication package @ Dataverse/Zenodo/etc. please use that (Github is NOT a “trusted” archive).</p>

<h2 id="more-information">More information</h2>

<p><a href="https://aeadataeditor.github.io/aea-de-guidance/preparing-for-pandp.html">Check out our full guidance on preparing for P&amp;P</a>.</p>]]></content><author><name>AEA Data Editor</name></author><category term="data editor tips" /><category term="replication packages" /><category term="Papers and Proceedings" /><category term="compliance" /><summary type="html"><![CDATA[For authors preparing the replication packages that accompany their 2026 AEA Papers and Proceedings publication www.aeaweb.org/journals/pandp: Here are some notes on preparing your replication package.]]></summary></entry><entry><title type="html">On the Dangers of Online Storage</title><link href="https://aeadataeditor.github.io/posts/2025-08-18-dropbox-etc" rel="alternate" type="text/html" title="On the Dangers of Online Storage" /><published>2025-08-18T00:00:00-04:00</published><updated>2025-08-18T00:00:00-04:00</updated><id>https://aeadataeditor.github.io/posts/dropbox-etc</id><content type="html" xml:base="https://aeadataeditor.github.io/posts/2025-08-18-dropbox-etc"><![CDATA[<p>We see this far too often: When we go to check the deposit that authors submit to us, all the files are there, but somewhere halfway through the process, the replicators hits one, then many files that are empty or … weird. What’s going on?</p>

<!-- more -->

<h2 id="the-problem">The Problem</h2>

<p>It turns out that online storage solutions, such as Dropbox, OneDrive, and Box (without necessarily limiting ourselves to these), provide a really “convenient” feature: They show you all the thousands of files you have accumulated, including over the 8 years this project has been underway. But they don’t want to put 2TB of data on your laptop. So the files you see are NOT really there… they leave placeholders in place.</p>

<p>What happens when you want to access these files? You double-click on them, and then it takes a bit longer for your Word, Acrobat, or Stata to open the file, because in the background, OneDropBoxDrive is quickly downloading the file for you, as if it had always been there. Sometimes, the application crashes, because OneDropBoxDrive is taking too long, but you try again, and it works. You think “huh, stupid computer”  and go on with your work.</p>

<p>So what happens when you zip up these files? Well, it turns out, in many cases (not entirely clear when), ZIP file creators are perfectly happy to NOT be patient, and simply zip up the placeholders. Which are empty files.</p>

<p>When you then upload these ZIP files to deposits like the AEA’s <a href="https://www.openicpsr.org/openicpsr/search/aea/studies">Data and Code Repository</a>, the system there happily unzips the ZIP file. And perfectly preserves a bunch of empty files.</p>

<p><img src="/images/icpsr-zero-byte-files.png" alt="Empty files on openICPSR" /></p>

<p>The problem is as bad on other repositories, such as the various Dataverses out there, or <a href="https://zenodo.org/">Zenodo</a>.</p>

<h2 id="the-partial-solution">The partial Solution</h2>

<p>We have added to our ingest scripts a <a href="https://github.com/AEADataEditor/replication-template/blob/master/automations/06_check_duplicates_and_zero_bytes.sh">check for zero-byte files</a>, which will flag these files. But this is relatively new, and not all replicators catch this early on. Leading to frustrating delays for everybody.</p>

<h2 id="the-solution">The Solution</h2>

<p>How do YOU (the author) avoid this problem? Two paths:</p>

<ul>
  <li>You could simply set the project directory to be “always available offline” (or whatever DriveBoxOneDrop may call it). So they gobble up all the storage space they need.  Then, when you ZIP them up, they will all be there. When you are done, you can flip them back to “online only” if you want (until you get back the report from us asking you to fix stuff…)</li>
  <li>Or, you can simply go to the BoxDriveDropOne website, and download the entire project from there, as a ZIP file, ready to upload.</li>
</ul>

<blockquote>
  <p>For Dropbox, here’s what you do:</p>

  <ul>
    <li>Go to <a href="https://www.dropbox.com/home">https://www.dropbox.com/home</a>. If you are not logged on there, go to your Dropbox icon in the system tray (Windows, Linux) or menu bar (Mac), and select “Launch Dropbox Website”.</li>
    <li>Navigate to the folder you want to download. You want to see the files in the folder (be “in”  the folder).</li>
  </ul>

  <p><img src="/images/dropbox-sample-folder.png" alt="Dropbox folder view" /></p>

  <ul>
    <li>Click on the gear icon ⚙️ to the right of the folder name, and select “Download”</li>
  </ul>

  <p><img src="/images/dropbox-sample-folder-download.png" alt="Dropbox download menu" /></p>
</blockquote>

<p>Voilà! You have a ZIP file with all the files in it, ready to upload to your deposit, with no chance at all that some files are missing.<sup id="fnref:a"><a href="#fn:a" class="footnote" rel="footnote" role="doc-noteref">1</a></sup></p>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:a">
      <p>Unless, of course, the files are missing on your DropOneBoxDrive, and the problem is not the software…. <a href="#fnref:a" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>AEA Data Editor</name></author><category term="data editor tips" /><category term="replication packages" /><category term="Dropbox" /><category term="OneDrive" /><category term="Box" /><summary type="html"><![CDATA[We see this far too often: When we go to check the deposit that authors submit to us, all the files are there, but somewhere halfway through the process, the replicators hits one, then many files that are empty or … weird. What’s going on?]]></summary></entry><entry><title type="html">On the use of Excel for reproducible tables</title><link href="https://aeadataeditor.github.io/posts/2025-01-17-tables-in-excel" rel="alternate" type="text/html" title="On the use of Excel for reproducible tables" /><published>2025-01-17T00:00:00-05:00</published><updated>2025-01-17T00:00:00-05:00</updated><id>https://aeadataeditor.github.io/posts/tables-in-excel</id><content type="html" xml:base="https://aeadataeditor.github.io/posts/2025-01-17-tables-in-excel"><![CDATA[<p>I sometimes see researchers doing much copy-pasting between output from Stata/R/MATLAB and Excel, to create tables. This is a lot of work, the source of many copy-paste errors, and a bad idea. I describe here one way to avoid this, even when the researcher does not want to invest in a new tool.</p>

<!-- more -->

<p>The typical table in economics papers will have up to 9 columns, and 5-25 rows. Seeking out, then copy-pasting up to 225 numbers per table is a lot of work, inhibits re-running of code (because “too complicated”), and is a source of errors. There are many packages out there that might allow you to construct a custom table in the programming language of your choice<sup id="fnref:note1"><a href="#fn:note1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup>, such as <strong>(Stata)</strong> <a href="http://repec.org/bocode/e/estout/estout.html">estout</a>,<sup id="fnref:estout"><a href="#fn:estout" class="footnote" rel="footnote" role="doc-noteref">2</a></sup> <a href="https://ideas.repec.org/c/boc/bocode/s456416.html">outreg2</a>,<sup id="fnref:outreg2"><a href="#fn:outreg2" class="footnote" rel="footnote" role="doc-noteref">3</a></sup> <a href="https://julianreif.com/regsave/">regsave</a>, <sup id="fnref:regsave"><a href="#fn:regsave" class="footnote" rel="footnote" role="doc-noteref">4</a></sup>, <strong>(R)</strong>  <a href="https://cran.r-project.org/web/packages/stargazer/">stargazer</a>,<sup id="fnref:stargazer"><a href="#fn:stargazer" class="footnote" rel="footnote" role="doc-noteref">5</a></sup>, <a href="https://modelsummary.com/">modelsummary</a>,<sup id="fnref:modelsummary"><a href="#fn:modelsummary" class="footnote" rel="footnote" role="doc-noteref">6</a></sup> and many others in R, Julia, Python, etc.</p>

<p>Here, however, I want to emphasize a custom approach that leverages what most people already know: how to use cell references in Excel. I combine a simple export of regression output to Excel sheets, combined with an Excel template. The replication package would contain the (possibly pre-populated) Excel template, and voilà! A reproducible table is born, and updated every time the code is re-run. While you might still need to update the table in your paper (or correctly <a href="https://answers.microsoft.com/en-us/msoffice/forum/all/insert-and-link-excel-table-to-word/8bffbcad-c9af-4725-a86f-0d650d168113">link an Excel sheet to Word</a> so that it also auto-updates…)</p>

<blockquote>
  <p>A more complete version, including with downloadable sample code and any improvements and error corrections, is available at <a href="https://larsvilhuber.github.io/writing-r-to-excel/">https://larsvilhuber.github.io/writing-r-to-excel/</a>.</p>
</blockquote>

<h2 id="the-example">The Example</h2>

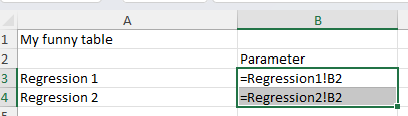
<p>The included file <a href="https://larsvilhuber.github.io/writing-r-to-excel/regression_results.xlsx"><code class="language-plaintext highlighter-rouge">regression_results.xlsx</code></a> has a tab called “My funny table”, which references the content of the two other tabs:</p>

<p><img src="https://larsvilhuber.github.io/writing-r-to-excel/excel-formula.png" alt="My funny table" /></p>

<p>The content of the two tabs <code class="language-plaintext highlighter-rouge">Regression1</code> and <code class="language-plaintext highlighter-rouge">Regression2</code> will be filled with the output from  two regressions. I have explicitly not set a seed, so that the values change very time you run the file. You can verify that the “funny table” is automatically updated with the latest results.</p>

<blockquote>
  <p>You can find the full code as a Quarto (R) file at <a href="https://github.com/larsvilhuber/writing-r-to-excel">https://github.com/larsvilhuber/writing-r-to-excel</a>.</p>
</blockquote>

<h2 id="setup">Setup</h2>

<p>Load required packages and set up environment. The package <a href="https://cran.r-project.org/web/packages/openxlsx/index.html">openxlsx</a> is used in preference to <code class="language-plaintext highlighter-rouge">writexl</code> because we explicitly want to preserve the contens of any existing (formatted!) Excel file.</p>

<div class="language-r highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">library</span><span class="p">(</span><span class="n">tidyverse</span><span class="p">)</span><span class="w">
</span></code></pre></div></div>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>── Attaching core tidyverse packages ──────────────────────── tidyverse 2.0.0 ──
✔ dplyr     1.1.4     ✔ readr     2.1.5
✔ forcats   1.0.0     ✔ stringr   1.5.1
✔ ggplot2   3.5.1     ✔ tibble    3.2.1
✔ lubridate 1.9.4     ✔ tidyr     1.3.1
✔ purrr     1.0.2     
── Conflicts ────────────────────────────────────────── tidyverse_conflicts() ──
✖ dplyr::filter() masks stats::filter()
✖ dplyr::lag()    masks stats::lag()
ℹ Use the conflicted package (&lt;http://conflicted.r-lib.org/&gt;) to force all conflicts to become errors
</code></pre></div></div>

<div class="language-r highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">library</span><span class="p">(</span><span class="n">openxlsx</span><span class="p">)</span><span class="w">
</span><span class="n">library</span><span class="p">(</span><span class="n">broom</span><span class="p">)</span><span class="w">
</span></code></pre></div></div>

<h2 id="data-generation">Data Generation</h2>

<p>Create sample datasets for the regression analyses.</p>

<div class="language-r highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># Create sample data for first regression</span><span class="w">
</span><span class="n">set.seed</span><span class="p">(</span><span class="m">123</span><span class="p">)</span><span class="w">
</span><span class="n">data1</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">tibble</span><span class="p">(</span><span class="w">
  </span><span class="n">x1</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="n">rnorm</span><span class="p">(</span><span class="m">100</span><span class="p">),</span><span class="w">
  </span><span class="n">x2</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="n">rnorm</span><span class="p">(</span><span class="m">100</span><span class="p">),</span><span class="w">
  </span><span class="n">y1</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="m">2</span><span class="o">*</span><span class="n">x1</span><span class="w"> </span><span class="o">+</span><span class="w"> </span><span class="m">0.5</span><span class="o">*</span><span class="n">x2</span><span class="w"> </span><span class="o">+</span><span class="w"> </span><span class="n">rnorm</span><span class="p">(</span><span class="m">100</span><span class="p">)</span><span class="w">
</span><span class="p">)</span><span class="w">

</span><span class="c1"># Create sample data for second regression</span><span class="w">
</span><span class="n">data2</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">tibble</span><span class="p">(</span><span class="w">
  </span><span class="n">z1</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="n">rnorm</span><span class="p">(</span><span class="m">100</span><span class="p">),</span><span class="w">
  </span><span class="n">z2</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="n">rnorm</span><span class="p">(</span><span class="m">100</span><span class="p">),</span><span class="w">
  </span><span class="n">z3</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="n">rnorm</span><span class="p">(</span><span class="m">100</span><span class="p">),</span><span class="w">
  </span><span class="n">y2</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="m">1.5</span><span class="o">*</span><span class="n">z1</span><span class="w"> </span><span class="o">-</span><span class="w"> </span><span class="m">0.8</span><span class="o">*</span><span class="n">z2</span><span class="w"> </span><span class="o">+</span><span class="w"> </span><span class="m">0.3</span><span class="o">*</span><span class="n">z3</span><span class="w"> </span><span class="o">+</span><span class="w"> </span><span class="n">rnorm</span><span class="p">(</span><span class="m">100</span><span class="p">)</span><span class="w">
</span><span class="p">)</span><span class="w">
</span></code></pre></div></div>

<h2 id="analysis">Analysis</h2>

<p>Perform regression analyses on both datasets.</p>

<div class="language-r highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># Run regressions</span><span class="w">
</span><span class="n">reg1</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">lm</span><span class="p">(</span><span class="n">y1</span><span class="w"> </span><span class="o">~</span><span class="w"> </span><span class="n">x1</span><span class="w"> </span><span class="o">+</span><span class="w"> </span><span class="n">x2</span><span class="p">,</span><span class="w"> </span><span class="n">data</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="n">data1</span><span class="p">)</span><span class="w">
</span><span class="n">reg2</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">lm</span><span class="p">(</span><span class="n">y2</span><span class="w"> </span><span class="o">~</span><span class="w"> </span><span class="n">z1</span><span class="w"> </span><span class="o">+</span><span class="w"> </span><span class="n">z2</span><span class="w"> </span><span class="o">+</span><span class="w"> </span><span class="n">z3</span><span class="p">,</span><span class="w"> </span><span class="n">data</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="n">data2</span><span class="p">)</span><span class="w">

</span><span class="c1"># Convert regression results to tidy format</span><span class="w">
</span><span class="n">reg1_results</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">tidy</span><span class="p">(</span><span class="n">reg1</span><span class="p">)</span><span class="w">
</span><span class="n">reg2_results</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">tidy</span><span class="p">(</span><span class="n">reg2</span><span class="p">)</span><span class="w">
</span></code></pre></div></div>

<h3 id="save-results">Save Results</h3>

<p>Depending on what you want to do, you could simply post-process the existing tables, creating a simple dataset that is printed. Here, we save the individual results as datasets.
If you were to split this document into three parts – <code class="language-plaintext highlighter-rouge">Data generation</code>, <code class="language-plaintext highlighter-rouge">Analysis</code>, and <code class="language-plaintext highlighter-rouge">Tables</code> – then this would be the last part of your analysis part.</p>

<div class="language-r highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># Save regression results as RDS files</span><span class="w">
</span><span class="n">saveRDS</span><span class="p">(</span><span class="n">reg1_results</span><span class="p">,</span><span class="w"> </span><span class="s2">"regression1_results.rds"</span><span class="p">)</span><span class="w">
</span><span class="n">saveRDS</span><span class="p">(</span><span class="n">reg2_results</span><span class="p">,</span><span class="w"> </span><span class="s2">"regression2_results.rds"</span><span class="p">)</span><span class="w">
</span></code></pre></div></div>

<h2 id="tables">Tables</h2>

<h3 id="formatting-results-via-excel">Formatting Results via Excel</h3>

<p>Here, however, we want to simulate what might be a far more complex table.</p>

<div class="language-r highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># Read data back in, as if we were a separate program</span><span class="w">

</span><span class="n">reg1_results</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">readRDS</span><span class="p">(</span><span class="s2">"regression1_results.rds"</span><span class="p">)</span><span class="w">
</span><span class="n">reg2_results</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">readRDS</span><span class="p">(</span><span class="s2">"regression2_results.rds"</span><span class="p">)</span><span class="w">
</span></code></pre></div></div>

<p>I use a function here, in order to handle the case when a file exists, and when one doesn’t. The very first time you would use this, no Excel file exists, but subsequent runs would overwrite the tabs within the existing file.</p>

<div class="language-r highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># Function to write to Excel, creating file if it doesn't exist</span><span class="w">
</span><span class="n">write_to_excel</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="k">function</span><span class="p">(</span><span class="n">results_list</span><span class="p">,</span><span class="w"> </span><span class="n">filename</span><span class="p">)</span><span class="w"> </span><span class="p">{</span><span class="w">
  </span><span class="c1"># Check if file exists</span><span class="w">
  </span><span class="k">if</span><span class="w"> </span><span class="p">(</span><span class="o">!</span><span class="n">file.exists</span><span class="p">(</span><span class="n">filename</span><span class="p">))</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="c1"># Create new workbook if file doesn't exist</span><span class="w">
    </span><span class="n">message</span><span class="p">(</span><span class="s2">"Creating new file"</span><span class="p">)</span><span class="w">
    </span><span class="n">wb</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">createWorkbook</span><span class="p">()</span><span class="w">
  </span><span class="p">}</span><span class="w"> </span><span class="k">else</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="c1"># Load existing workbook if file exists</span><span class="w">
    </span><span class="n">message</span><span class="p">(</span><span class="s2">"Re-using existing file"</span><span class="p">)</span><span class="w">
    </span><span class="n">wb</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">loadWorkbook</span><span class="p">(</span><span class="n">filename</span><span class="p">)</span><span class="w">
  </span><span class="p">}</span><span class="w">
  
  </span><span class="c1"># Loop through the results list and write/overwrite sheets</span><span class="w">
  </span><span class="k">for</span><span class="w"> </span><span class="p">(</span><span class="n">sheet_name</span><span class="w"> </span><span class="k">in</span><span class="w"> </span><span class="nf">names</span><span class="p">(</span><span class="n">results_list</span><span class="p">))</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="c1"># Remove sheet if it already exists</span><span class="w">
    </span><span class="k">if</span><span class="w"> </span><span class="p">(</span><span class="n">sheet_name</span><span class="w"> </span><span class="o">%in%</span><span class="w"> </span><span class="nf">names</span><span class="p">(</span><span class="n">wb</span><span class="p">))</span><span class="w"> </span><span class="p">{</span><span class="w">
      </span><span class="n">removeWorksheet</span><span class="p">(</span><span class="n">wb</span><span class="p">,</span><span class="w"> </span><span class="n">sheet_name</span><span class="p">)</span><span class="w">
    </span><span class="p">}</span><span class="w">
    </span><span class="c1"># Add new worksheet</span><span class="w">
    </span><span class="n">addWorksheet</span><span class="p">(</span><span class="n">wb</span><span class="p">,</span><span class="w"> </span><span class="n">sheet_name</span><span class="p">)</span><span class="w">
    </span><span class="c1"># Write data to worksheet</span><span class="w">
    </span><span class="n">writeData</span><span class="p">(</span><span class="n">wb</span><span class="p">,</span><span class="w"> </span><span class="n">sheet_name</span><span class="p">,</span><span class="w"> </span><span class="n">results_list</span><span class="p">[[</span><span class="n">sheet_name</span><span class="p">]])</span><span class="w">
  </span><span class="p">}</span><span class="w">
  
  </span><span class="c1"># Save workbook</span><span class="w">
  </span><span class="n">saveWorkbook</span><span class="p">(</span><span class="n">wb</span><span class="p">,</span><span class="w"> </span><span class="n">filename</span><span class="p">,</span><span class="w"> </span><span class="n">overwrite</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="kc">TRUE</span><span class="p">)</span><span class="w">
</span><span class="p">}</span><span class="w">

</span><span class="c1"># Create list of results</span><span class="w">
</span><span class="n">regression_results</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="nf">list</span><span class="p">(</span><span class="w">
  </span><span class="s2">"Regression1"</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="n">reg1_results</span><span class="p">,</span><span class="w">
  </span><span class="s2">"Regression2"</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="n">reg2_results</span><span class="w">
</span><span class="p">)</span><span class="w">

</span><span class="c1"># Write to Excel file</span><span class="w">
</span><span class="n">write_to_excel</span><span class="p">(</span><span class="n">regression_results</span><span class="p">,</span><span class="w"> </span><span class="s2">"regression_results.xlsx"</span><span class="p">)</span><span class="w">
</span></code></pre></div></div>

<h3 id="display-results-here">Display Results Here</h3>

<p>Show the regression results in the document.</p>

<div class="language-r highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># Display results from first regression</span><span class="w">

</span><span class="n">knitr</span><span class="o">::</span><span class="n">kable</span><span class="p">(</span><span class="n">reg1_results</span><span class="p">)</span><span class="w">
</span></code></pre></div></div>

<table>
  <thead>
    <tr>
      <th style="text-align: left">term</th>
      <th style="text-align: right">estimate</th>
      <th style="text-align: right">std.error</th>
      <th style="text-align: right">statistic</th>
      <th style="text-align: right">p.value</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left">(Intercept)</td>
      <td style="text-align: right">0.1350654</td>
      <td style="text-align: right">0.0961401</td>
      <td style="text-align: right">1.404882</td>
      <td style="text-align: right">0.1632508</td>
    </tr>
    <tr>
      <td style="text-align: left">x1</td>
      <td style="text-align: right">1.8668285</td>
      <td style="text-align: right">0.1048695</td>
      <td style="text-align: right">17.801445</td>
      <td style="text-align: right">0.0000000</td>
    </tr>
    <tr>
      <td style="text-align: left">x2</td>
      <td style="text-align: right">0.5238113</td>
      <td style="text-align: right">0.0989947</td>
      <td style="text-align: right">5.291307</td>
      <td style="text-align: right">0.0000008</td>
    </tr>
  </tbody>
</table>

<div class="language-r highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># Display results from second regression</span><span class="w">

</span><span class="n">knitr</span><span class="o">::</span><span class="n">kable</span><span class="p">(</span><span class="n">reg2_results</span><span class="p">)</span><span class="w">
</span></code></pre></div></div>

<table>
  <thead>
    <tr>
      <th style="text-align: left">term</th>
      <th style="text-align: right">estimate</th>
      <th style="text-align: right">std.error</th>
      <th style="text-align: right">statistic</th>
      <th style="text-align: right">p.value</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left">(Intercept)</td>
      <td style="text-align: right">-0.1563012</td>
      <td style="text-align: right">0.1048648</td>
      <td style="text-align: right">-1.490501</td>
      <td style="text-align: right">0.1393709</td>
    </tr>
    <tr>
      <td style="text-align: left">z1</td>
      <td style="text-align: right">1.4305458</td>
      <td style="text-align: right">0.1009734</td>
      <td style="text-align: right">14.167548</td>
      <td style="text-align: right">0.0000000</td>
    </tr>
    <tr>
      <td style="text-align: left">z2</td>
      <td style="text-align: right">-0.7925999</td>
      <td style="text-align: right">0.1079181</td>
      <td style="text-align: right">-7.344456</td>
      <td style="text-align: right">0.0000000</td>
    </tr>
    <tr>
      <td style="text-align: left">z3</td>
      <td style="text-align: right">0.2206171</td>
      <td style="text-align: right">0.1141786</td>
      <td style="text-align: right">1.932210</td>
      <td style="text-align: right">0.0562816</td>
    </tr>
  </tbody>
</table>

<h3 id="directory-contents">Directory Contents</h3>

<p>Show files created in the working directory.</p>

<div class="language-r highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># List all files in current working directory</span><span class="w">
</span><span class="n">list.files</span><span class="p">(</span><span class="n">pattern</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="s2">"(xlsx|rds)$"</span><span class="p">)</span><span class="w">
</span></code></pre></div></div>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>[1] "regression_results.xlsx"          "regression_results_template.xlsx"
[3] "regression1_results.rds"          "regression2_results.rds"         
</code></pre></div></div>

<h2 id="housekeeping">Housekeeping</h2>

<div class="language-r highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">sessionInfo</span><span class="p">()</span><span class="w">
</span></code></pre></div></div>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>R version 4.4.2 (2024-10-31 ucrt)
Platform: x86_64-w64-mingw32/x64
Running under: Windows 11 x64 (build 26100)

Matrix products: default


locale:
[1] LC_COLLATE=English_United States.utf8 
[2] LC_CTYPE=English_United States.utf8   
[3] LC_MONETARY=English_United States.utf8
[4] LC_NUMERIC=C                          
[5] LC_TIME=English_United States.utf8    

time zone: America/Toronto
tzcode source: internal

attached base packages:
[1] stats     graphics  grDevices datasets  utils     methods   base     

other attached packages:
 [1] broom_1.0.7      openxlsx_4.2.7.1 lubridate_1.9.4  forcats_1.0.0   
 [5] stringr_1.5.1    dplyr_1.1.4      purrr_1.0.2      readr_2.1.5     
 [9] tidyr_1.3.1      tibble_3.2.1     ggplot2_3.5.1    tidyverse_2.0.0 

loaded via a namespace (and not attached):
 [1] gtable_0.3.6      jsonlite_1.8.9    compiler_4.4.2    renv_1.0.11      
 [5] zip_2.3.1         Rcpp_1.0.13-1     tidyselect_1.2.1  scales_1.3.0     
 [9] yaml_2.3.10       fastmap_1.2.0     R6_2.5.1          generics_0.1.3   
[13] knitr_1.49        backports_1.5.0   munsell_0.5.1     pillar_1.9.0     
[17] tzdb_0.4.0        rlang_1.1.4       utf8_1.2.4        stringi_1.8.4    
[21] xfun_0.49         timechange_0.3.0  cli_3.6.3         withr_3.0.2      
[25] magrittr_2.0.3    digest_0.6.37     grid_4.4.2        rstudioapi_0.17.1
[29] hms_1.1.3         lifecycle_1.0.4   vctrs_0.6.5       evaluate_1.0.1   
[33] glue_1.8.0        fansi_1.0.6       colorspace_2.1-1  rmarkdown_2.29   
[37] tools_4.4.2       pkgconfig_2.0.3   htmltools_0.5.8.1
</code></pre></div></div>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:note1">
      <p>The same basic toolkit can be used to construct the figure of your choice, but I’ll concentrate on tables here. <a href="#fnref:note1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:estout">
      <p>Jann, Ben (2005): Making regression tables from stored estimates. The Stata Journal 5(3): 288-308 and Jann, Ben (2007): Making regression tables simplified. The Stata Journal 7(2): 227-244. <a href="#fnref:estout" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:outreg2">
      <p>Roy Wada, 2005. “<a href="https://ideas.repec.org/c/boc/bocode/s456416.html">OUTREG2: Stata module to arrange regression outputs into an illustrative table</a>,” Statistical Software Components S456416, Boston College Department of Economics, revised 17 Aug 2014. <a href="#fnref:outreg2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:regsave">
      <p>Julian Reif, 2008. “<a href="https://ideas.repec.org/c/boc/bocode/s456964.html">REGSAVE: Stata module to save regression results to a Stata-formatted dataset</a>,” Statistical Software Components S456964, Boston College Department of Economics, revised 03 Dec 2023. <a href="#fnref:regsave" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:stargazer">
      <p>Hlavac M (2022). stargazer: Well-Formatted Regression and Summary Statistics Tables. Social Policy Institute, Bratislava, Slovakia. R package version 5.2.3, <a href="https://CRAN.R-project.org/package=stargazer">https://CRAN.R-project.org/package=stargazer</a>. <a href="#fnref:stargazer" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:modelsummary">
      <p>Arel-Bundock V (2022). “modelsummary: Data and Model Summaries in R.” Journal of Statistical Software, 103(1), 1–23. <a href="https://doi.org/10.18637/jss.v103.i01">https://doi.org/10.18637/jss.v103.i01</a>. <a href="#fnref:modelsummary" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>AEA Data Editor</name></author><category term="data editor tips" /><category term="replication packages" /><category term="code" /><category term="Excel" /><summary type="html"><![CDATA[I sometimes see researchers doing much copy-pasting between output from Stata/R/MATLAB and Excel, to create tables. This is a lot of work, the source of many copy-paste errors, and a bad idea. I describe here one way to avoid this, even when the researcher does not want to invest in a new tool.]]></summary></entry><entry><title type="html">How to respond to data provider requests for data removal (take-down requests)</title><link href="https://aeadataeditor.github.io/posts/2024-11-01-psid-requests" rel="alternate" type="text/html" title="How to respond to data provider requests for data removal (take-down requests)" /><published>2024-11-01T00:00:00-04:00</published><updated>2024-11-01T00:00:00-04:00</updated><id>https://aeadataeditor.github.io/posts/psid-requests</id><content type="html" xml:base="https://aeadataeditor.github.io/posts/2024-11-01-psid-requests"><![CDATA[<p>The <a href="https://www.aeaweb.org/journals/data/data-code-policy">AEA Data and Code Availability Policy</a> asks that authors provide access to all data used in a published paper. But it also acknowledges that there are cases where data cannot be shared. This may be due to privacy concerns, proprietary rights to the data that are not the author’s, or terms of use that prohibit the sharing, redistribution, or publication of data.</p>

<p>So what happens when an author inadvertently does share such data, and the data provider finds out, and is not happy? Let’s call this a “take-down request.” The data provider asks that the author remove the data from the replication package. But the author is committed (by <a href="https://www.aeaweb.org/journals/forms/data-code-archive-agreement">signing an agreement</a>) to not withdrawing the replication package. How to proceed? Read on!</p>

<!-- more -->

<h2 id="in-a-nutshell">In a nutshell</h2>

<p>The gist of the solution is the following, for AEA manuscripts (which I obviously know well), but probably similarly for other journals:</p>

<ul>
  <li>Remove the infringing data from V1 of the replication package.</li>
  <li>[Ideally] Create a new, separate deposit that is in compliance with the data provider’s terms of use.</li>
  <li>Document the new location of the now absent data in the README of the replication package.</li>
  <li>Submit the revised replication package to the journal.</li>
  <li>The journal publishes V2 of the replication package, which is now compliant.</li>
</ul>

<h2 id="an-example-psid-data">An example: PSID data</h2>

<p>For years, I as Data Editor have alerted authors when I detected data that infringes on terms of use. Two of the most frequent cases are the Panel Study of Income Dynamics (PSID) and the UNSD’s Comtrade data. We even have an <a href="https://www.aeaweb.org/journals/data/faq#psid">FAQ entry dedicated to the PSID case</a> and a <a href="https://github.com/AEADataEditor/replication-template/blob/master/sample-language-report.md?plain=1#L243">copy-and-paste entry in our “most frequent errors” document</a>.</p>

<p>But what if PSID data does end up in a deposit, either because I missed it (believe it or not, I’m not perfect), or because the replication package was published before the Data Editor was appointed?<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup> In fact, on November 1, 2024, the folks at PSID did just that: Contacted a large number of authors that had included PSID data in their replication packages, asking them to remove the data.</p>

<p>It is worth reminding that the <a href="https://simba.isr.umich.edu/U/CondUse.aspx">PSID terms of use</a>, which everybody agrees to when downloading the data, are quite clear:</p>

<blockquote>
  <ol>
    <li>Not transfer PSID public data that has been downloaded from the website, including user-created data extracts, to any third parties…</li>
  </ol>
</blockquote>

<blockquote>
  <p>So what can authors do?</p>
</blockquote>

<h3 id="preliminary-steps">Preliminary steps</h3>

<p>The first steps involve getting access to your own replication package. This may differ by when the replication package was published.<sup id="fnref:2"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup></p>

<ul>
  <li>For authors with papers published before 2019 (approximately)
    <ul>
      <li>All authors will need to get an openICPSR login, which will serve them both for the changes to the AEA and for creating the new PSID deposit.</li>
      <li>They will need to request access to the deposit. The <a href="https://www.openicpsr.org/openicpsr/contactUs">openICPSR helpdesk</a> may be able to help with that. The authors should mention the URL or DOI, and the openICPSR login they want the deposit associated with.</li>
    </ul>
  </li>
  <li>
    <p>For authors with more recent papers:</p>

    <ul>
      <li>They will need to re-create an ICPSR account <strong>with the same email as previously used</strong> since <a href="https://researcherpassport.icpsr.umich.edu/help">ICPSR changed their login system in Feb 2024</a>. The <a href="https://www.openicpsr.org/openicpsr/contactUs">openICPSR helpdesk</a> may help with that.</li>
      <li>They need to then <a href="https://www.aeaweb.org/journals/data/revisions-policy#createnewversion">create a new version</a>.</li>
    </ul>
  </li>
</ul>

<p><img src="/images/icpsr-create-new-version.png" alt="Create a new version" />]</p>

<h3 id="rules-that-apply-to-revisions-of-replication-packages">Rules that apply to revisions of replication packages</h3>

<p>Here are a few simple rules:</p>

<ul>
  <li>The modified package should differ only as necessary from the original package. Less work for the author, greater clarity for replicators, everybody wins.</li>
  <li>Journal-specific policies may apply. For instance, the AEA has a <a href="https://www.aeaweb.org/journals/data/revisions-policy">Policy on Revisions of Data and Code Deposits in the AEA Data and Code Repository</a>. Among other things, it requires that all changes be clearly identified.</li>
</ul>

<h3 id="fixing-the-problem">Fixing the problem</h3>

<p>Once the preliminaries are done, here’s what authors need to do to remain compliant with AEA policy (similar rules may apply at other journals):</p>

<ul>
  <li>PSID actually has a way to properly and openly preserve the user-created extracts in compliance with their terms of use. It is the <a href="https://www.openicpsr.org/openicpsr/psid">PSID Repository on openICPSR</a>.</li>
  <li>For sake of discussion, the “original replication package” is V1. The replacement replication package will be V2.</li>
</ul>

<p><img src="/images/psid-repository.png" alt="Image of PSID repository" /></p>

<ul>
  <li>For sake of discussion, consider the case where V1 contains a single file <code class="language-plaintext highlighter-rouge">psid.dta</code>.</li>
</ul>

<h4 id="psid-deposit">PSID deposit</h4>

<ul>
  <li>Authors should <a href="https://www.openicpsr.org/openicpsr/psid/deposit-instructions">create a new deposit at the PSID repository</a> with title “<strong>Supplementary data</strong> for: [NAME OF THE MANUSCRIPT]”.
    <ul>
      <li>Put into it ONLY the PSID data <code class="language-plaintext highlighter-rouge">psid.dta</code>. Do not put other things into this deposit.</li>
      <li>You might want to add the <strong>DOI</strong> of V1 and the <strong>DOI</strong> of the manuscript in the “Related publications” section  (use the <code class="language-plaintext highlighter-rouge">Import from DOI</code> functionality, choose <code class="language-plaintext highlighter-rouge">is supplemented by</code> for the <code class="language-plaintext highlighter-rouge">Relationship</code> field)</li>
      <li>Publish it.</li>
      <li>Remember the DOI (not the URL). Call this the “[PSID DOI]”. Replace this with the <strong>actual</strong> DOI everywhere it is mentioned below!</li>
    </ul>
  </li>
</ul>

<h4 id="back-in-the-aea-deposit">Back in the AEA deposit</h4>

<ul>
  <li>Log on to the V1 deposit. You should be in “Modifying” mode.</li>
  <li>Remove (delete) the same PSID data (<code class="language-plaintext highlighter-rouge">psid.dta</code>) you just uploaded into the PSID deposit, from the openICPSR AEA deposit V1.</li>
  <li>Update the README with “PSID data for this package can be obtained from [PSID DOI]” in an appropriate location. The ideal README follows the <a href="https://doi.org/10.5281/zenodo.7293838">Template README published by the Social Science Data Editors</a>, but make only minimal changes to the README in this deposit.
    <ul>
      <li>Delete the old README (<em>completely</em>),</li>
      <li>Upload the new README (in PDF format) to the same location the original one was</li>
    </ul>
  </li>
  <li><a href="https://www.aeaweb.org/journals/data/revisions-policy#identifying">Create a <code class="language-plaintext highlighter-rouge">CHANGES.txt</code>.</a>  Identify changes made. E.g. “V2: Moved PSID data to [PSID DOI]”.  It should look something like this:</li>
</ul>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>V1: Original deposit
V2: PSID data moved to [PSID DOI]
</code></pre></div></div>
<ul>
  <li>Upload the <code class="language-plaintext highlighter-rouge">CHANGES.txt</code>.</li>
  <li>Link to the [PSID DOI] in the “Related publications” section of the deposit (use the <code class="language-plaintext highlighter-rouge">Import from DOI</code> functionality, choose <code class="language-plaintext highlighter-rouge">is supplemented by</code> for the <code class="language-plaintext highlighter-rouge">Relationship</code> field)</li>
  <li>You <em>may</em> have to add the “manuscript number” to the metadata, see <a href="https://aeadataeditor.github.io/aea-de-guidance/data-deposit-aea.html#scope-of-project-section">this link</a>. Use the last part of the DOI of the paper, e.g. if the paper DOI is <code class="language-plaintext highlighter-rouge">https://doi.org/10.1257/aer.p20161120</code> then the “manuscript number” should be <code class="language-plaintext highlighter-rouge">aer.p20161120</code>.</li>
  <li><a href="https://aeadataeditor.github.io/aea-de-guidance/data-deposit-aea.html#submitting-to-the-data-editor">Re-Submit to the AEA</a></li>
  <li>Contact the <a href="https://www.openicpsr.org/openicpsr/contactUs">openICPSR helpdesk</a> and ask them to “Unpublish” the V1 deposit.</li>
</ul>

<p><img src="/images/project-submit.png" alt="(Re-)Submit to the AEA" /></p>

<h3 id="the-end-state">The end state</h3>

<p>After all the fixes,</p>

<ul>
  <li>V1 is still visible, but can no longer be downloaded.</li>
</ul>

<p><img src="/images/openICPSR-study-unpublished.png" alt="Unpublished deposit shows banner" /></p>

<ul>
  <li>the PSID deposit is now available. Users who want to download the data have to agree to the PSID’s terms of use. You are now in compliance with the PSID’s terms of use!</li>
  <li>V2 is published, contains no PSID data, links to the PSID deposit, and remains otherwise available to replicators. You are still in compliance with the AEA publication agreements and your obligations as an AEA author!</li>
</ul>

<h3 id="an-example">An example</h3>

<p>Fran Blau and Larry Kahn had a JEL article (with replication package!) back in 2016:</p>

<blockquote>
  <p>Blau, Francine D., and Lawrence M. Kahn. “The Gender Wage Gap: Extent, Trends, and Explanations.” Journal of Economic Literature 55, no. 3 (September 2017): 789–865. <a href="https://doi.org/10.1257/jel.20160995">https://doi.org/10.1257/jel.20160995</a>.</p>
</blockquote>

<p>The relevant original replication package was migrated to openICPSR in 2019, and its contents can still be viewed here, <strong>but not downloaded</strong>:</p>

<blockquote>
  <p>Blau, Francine D., and Kahn, Lawrence M. Replication data for: The Gender Wage Gap: Extent, Trends, and Explanations. Nashville, TN: American Economic Association [publisher], 2017. Ann Arbor, MI: Inter-university Consortium for Political and Social Research [distributor], 2019-10-12. <a href="https://doi.org/10.3886/E113913V1">https://doi.org/10.3886/E113913V1</a></p>
</blockquote>

<p>The amended replication package is now available, and linked from the earlier one (note the V2, and the later publication date):</p>

<blockquote>
  <p>Blau, Francine D., and Kahn, Lawrence M. Replication data for: The Gender Wage Gap: Extent, Trends, and Explanations. Nashville, TN: American Economic Association [publisher], 2024. Ann Arbor, MI: Inter-university Consortium for Political and Social Research [distributor], 2024-11-14. <a href="https://doi.org/10.3886/E113913V2">https://doi.org/10.3886/E113913V2</a></p>
</blockquote>

<p>The required <code class="language-plaintext highlighter-rouge">CHANGES.txt</code> reads</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>V1: Original version
V2: Moved PSID data to https://doi.org/10.3886/E210483V1 and updated README.
</code></pre></div></div>

<p>and the new PSID deposit is referenced there, in the related publications, and in the README.</p>

<blockquote>
  <p>Kahn, Lawrence, and Francine Blau. “Supplementary for: Francine D. Blau and Lawrence M. Kahn, ‘The Gender Wage Gap: Extent, Trends, and Explanations’, Journal of Economic Literature , 55 ,3 (Sept 2017): 789-865.” ICPSR - Interuniversity Consortium for Political and Social Research, 2024. <a href="https://doi.org/10.3886/E210483V1">https://doi.org/10.3886/E210483V1</a>.<sup id="fnref:note"><a href="#fn:note" class="footnote" rel="footnote" role="doc-noteref">3</a></sup></p>
</blockquote>

<h3 id="conclusion">Conclusion</h3>

<p>The problem outlined above is not unique to the PSID. We have seen “takedown” requests from the German Socio-Economic Panel and others, and I have prevented inadvertent publication of UNSD Comtrade data, Compustat data, commercial data, PII-laden data, etc. The PSID is relatively unique in that it has a mechanism to actually preserve the author-created extracts. A few other such mechanisms exist, but they are by no means universal. Most “takedown” requests can only be satisfied with the deletion of data, and the inclusion of detailed information on how others can obtain the data from the original data provider - an error-prone and not ideal process.</p>

<p>Authors should feel free to reach out to their journal’s data and reproducibility editor with questions about the available options.</p>
<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p>I was appointed as Data Editor position  in 2018, and we started verification of packages in 2019. We also only do a cursory review of Papers and Proceedings, though they remain subject to the same Data and Code Availability Policy. <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2">
      <p>The dividing line is approximately Oct 1, 2019. In 2019, <a href="https://aeadataeditor.github.io/aea-supplement-migration/programs/aea201910-migration.html">we migrated approximately 2,500 older replication packages into openICPSR</a>. Authors were not involved in this process, and so do not have operational access to the replication package. They do, however, have ownership of the deposit, and can request access to it. <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:note">
      <p>A shorter and perfectly acceptable name would have been “Supplementary for: The Gender Wage Gap: Extent, Trends, and Explanations”. The supplementary data could also be linked back to the original replication package, for clarity. <a href="#fnref:note" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>AEA Data Editor</name></author><category term="data editor tips" /><category term="replication packages" /><category term="terms of use" /><summary type="html"><![CDATA[The AEA Data and Code Availability Policy asks that authors provide access to all data used in a published paper. But it also acknowledges that there are cases where data cannot be shared. This may be due to privacy concerns, proprietary rights to the data that are not the author’s, or terms of use that prohibit the sharing, redistribution, or publication of data. So what happens when an author inadvertently does share such data, and the data provider finds out, and is not happy? Let’s call this a “take-down request.” The data provider asks that the author remove the data from the replication package. But the author is committed (by signing an agreement) to not withdrawing the replication package. How to proceed? Read on!]]></summary></entry><entry><title type="html">On the use and reuse of within-project code</title><link href="https://aeadataeditor.github.io/posts/2024-07-19-functions-and-code-duplication" rel="alternate" type="text/html" title="On the use and reuse of within-project code" /><published>2024-07-19T00:00:00-04:00</published><updated>2024-07-19T00:00:00-04:00</updated><id>https://aeadataeditor.github.io/posts/functions-and-code-duplication</id><content type="html" xml:base="https://aeadataeditor.github.io/posts/2024-07-19-functions-and-code-duplication"><![CDATA[<p>We often see researchers handle variants of their analysis by copying and pasting code, or by copying code files into separate directories, and making only minimal modifications. Some folks do this for robustness checks - same data, different analysis method, or a variant of the dependent variable - others for simulation of various scenarios - an economy without banks, an economy with credit-constrained banks, an economy with unconstrained banks. I won’t point to particular examples, to protect the (somewhat) innocent, but this is not a good idea.</p>

<!-- more -->

<p>It introduces lots of failure points - not necessarily in the final package, but in the development process.</p>

<h2 id="the-example">The example</h2>

<p>Consider that you are halfway through your project. You have a base model, and three variants thereof. Each of which is the base model, copied into three different directories, with minimal modifications in the code. For sake of clarity, and with no loss of generality intended:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>code/
    base-model/
            base-model.m
    robustness-check-1/
            base-model.m
    robustness-check-2/
            base-model.m
    robustness-check-3/
            base-model.m
</code></pre></div></div>

<p>where a <code class="language-plaintext highlighter-rouge">diff</code> between <code class="language-plaintext highlighter-rouge">base-model.m</code> and <code class="language-plaintext highlighter-rouge">robustness-check-1/base-model.m</code> would show only a few lines changed:</p>

<div class="language-diff highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="gh">diff code/base-model/base-model.m code/robustness-check-1/base-model.m
</span><span class="p">13073c13073
</span><span class="gd">&lt; a=1;
</span><span class="p">---
</span><span class="gi">&gt; a=2;
</span></code></pre></div></div>

<blockquote>
  <p>Note: the change would appear to be in line 13073, which is awfully subtle… this is inspired by real-life examples!</p>
</blockquote>

<h2 id="the-problem">The problem</h2>

<p>Now imagine that your thesis advisor, or a reviewer, identifies a key problem in the implemented algorithm. You fix it in <code class="language-plaintext highlighter-rouge">base-model.m</code>, but now need to fix it in all the other modified copies too. Will there be any typos when you implement the patch? What if there are not three robustness checks, but 30? Or 300 different parameterizations of a simulation?</p>

<p>The techy programmer might decide to do this with <code class="language-plaintext highlighter-rouge">patch</code> in conjunction with <code class="language-plaintext highlighter-rouge">git</code>, but that already counts as advanced functionality (I probably lost a lot of readers with the first part of that sentence…)</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># create a patch from the updates to the base model</span>
git diff d362f6..3bd22 <span class="o">&gt;</span> patch.diff
<span class="c"># apply the patch to the robustness check</span>
patch code/robustness-check-1/base-model.m &lt; patch.diff
</code></pre></div></div>

<p>but that is not a robust solution that scales to the 30 or 300 robustness checks.</p>

<h2 id="a-possible-solution">A possible solution</h2>

<p>The core solution is to apply elementary best programming practices: <strong>write functions</strong>.<sup id="fnref:functions"><a href="#fn:functions" class="footnote" rel="footnote" role="doc-noteref">1</a></sup></p>

<p>So should one go about the above problem? My rule of thumb is:</p>

<ul>
  <li>Copy code once, fine, don’t do it again.</li>
  <li>Copy it twice, stop, and create a function.</li>
  <li>Copy it three times: don’t even go there!</li>
</ul>

<p>Assuming that you are using MATLAB (where we seem to see this often), you should treat the core model code as a “function” (even if you do not explicitly program it that way), and then call that “function” multiple times. In a nutshell:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>code/
    core-simulation/
            parametrized-simulation.m
    base-model.m
    robustness-check-1.m
    robustness-check-2.m
    robustness-check-3.m
</code></pre></div></div>

<p>where</p>

<div class="language-matlab highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1">% base-model.m</span>

<span class="c1">% We set the base model to have the following parameters,</span>
<span class="c1">% as per Section 2 of the paper:</span>
<span class="n">a</span><span class="o">=</span><span class="mi">1</span><span class="p">;</span>
<span class="n">b</span><span class="o">=</span><span class="mi">2</span><span class="p">;</span>
<span class="n">c</span><span class="o">=</span><span class="mi">3</span><span class="p">;</span>

<span class="c1">% We then call the core simulation code</span>
<span class="n">parametrized</span><span class="o">-</span><span class="n">simulation</span>
</code></pre></div></div>

<p>will call the code in “parametrized-simulation.m” with parameters <code class="language-plaintext highlighter-rouge">a,b,c</code> already set. The simulation itself assumes those parameters are set.<sup id="fnref:proper-function"><a href="#fn:proper-function" class="footnote" rel="footnote" role="doc-noteref">2</a></sup></p>

<p>The robustness checks might then have</p>

<div class="language-matlab highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1">% robustness-check-1.m</span>

<span class="c1">% We set the model to have the following parameters,</span>
<span class="c1">% as per Section 3 of the paper:</span>

<span class="n">a</span><span class="o">=</span><span class="mi">2</span><span class="p">;</span> <span class="c1">% This differs from the base model</span>
<span class="n">b</span><span class="o">=</span><span class="mi">2</span><span class="p">;</span>
<span class="n">c</span><span class="o">=</span><span class="mi">3</span><span class="p">;</span>

<span class="c1">% We then call the core simulation code</span>
<span class="n">parametrized</span><span class="o">-</span><span class="n">simulation</span>
</code></pre></div></div>

<p>or go through a loop of multiple values:</p>

<div class="language-matlab highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1">% robustness-check-2.m</span>


<span class="c1">% We set the model to have the following parameters,</span>
<span class="c1">% as per Section 4 of the paper:</span>

<span class="n">b</span><span class="o">=</span><span class="mi">3</span><span class="p">;</span>
<span class="n">c</span><span class="o">=</span><span class="mi">4</span><span class="p">;</span>

<span class="c1">% We now explore the space of a within this context.</span>
<span class="k">for</span> <span class="n">a</span> <span class="o">=</span> <span class="mi">1</span><span class="p">:</span><span class="mi">10</span>
    <span class="n">parametrized</span><span class="o">-</span><span class="n">simulation</span>
<span class="k">end</span>

<span class="c1">% Summarize results from exploration</span>

<span class="n">summarize</span><span class="o">-</span><span class="n">results</span>

</code></pre></div></div>

<h2 id="other-languages">Other languages</h2>

<p>Is that a MATLAB-specific problem? No. We see similar issues in Stata, R, Python, and other languages. The core solution is the same: write functions, and call them multiple times, instead of copying code around, and hard-coding parameters.</p>

<h2 id="other-situations">Other situations</h2>

<p>The above example had continuous (well, kind of) parameter spaces. What if they are discontinuous? You can still loop over a whole set of specifications by storing them in a file - yes, an Excel file is fine! - and reading them in (in MATLAB, <a href="https://www.mathworks.com/help/matlab/import_export/ways-to-import-spreadsheets.html"><code class="language-plaintext highlighter-rouge">readtable</code></a>). For example,</p>

<div class="language-matlab highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1">% Read the Excel spreadsheet</span>
<span class="p">[</span><span class="n">num</span><span class="p">,</span> <span class="n">txt</span><span class="p">,</span> <span class="n">raw</span><span class="p">]</span> <span class="o">=</span> <span class="nb">xlsread</span><span class="p">(</span><span class="s1">'your_spreadsheet.xlsx'</span><span class="p">);</span>

<span class="c1">% Get the number of rows in the data</span>
<span class="p">[</span><span class="n">numRows</span><span class="p">,</span> <span class="o">~</span><span class="p">]</span> <span class="o">=</span> <span class="nb">size</span><span class="p">(</span><span class="n">raw</span><span class="p">);</span>

<span class="c1">% Loop over each row, starting from the second row (assuming first row is header)</span>
<span class="k">for</span> <span class="n">i</span> <span class="o">=</span> <span class="mi">2</span><span class="p">:</span><span class="n">numRows</span>
    <span class="c1">% Extract values from columns A, B, and C</span>
    <span class="n">a</span> <span class="o">=</span> <span class="n">raw</span><span class="p">{</span><span class="n">i</span><span class="p">,</span> <span class="mi">1</span><span class="p">};</span>  <span class="c1">% Column A</span>
    <span class="n">b</span> <span class="o">=</span> <span class="n">raw</span><span class="p">{</span><span class="n">i</span><span class="p">,</span> <span class="mi">2</span><span class="p">};</span>  <span class="c1">% Column B</span>
    <span class="n">c</span> <span class="o">=</span> <span class="n">raw</span><span class="p">{</span><span class="n">i</span><span class="p">,</span> <span class="mi">3</span><span class="p">};</span>  <span class="c1">% Column C</span>
    
    <span class="c1">% Call the function something() with the extracted values</span>
    <span class="nb">result</span> <span class="o">=</span> <span class="n">something</span><span class="p">(</span><span class="n">a</span><span class="p">,</span> <span class="n">b</span><span class="p">,</span> <span class="n">c</span><span class="p">);</span>
    
    <span class="c1">% You can do something with the result here if needed</span>
    <span class="c1">% For example, store it in an array or print it</span>
    <span class="nb">disp</span><span class="p">([</span><span class="s1">'Result for row '</span><span class="p">,</span> <span class="nb">num2str</span><span class="p">(</span><span class="n">i</span><span class="p">),</span> <span class="s1">': '</span><span class="p">,</span> <span class="nb">num2str</span><span class="p">(</span><span class="nb">result</span><span class="p">)]);</span>
<span class="k">end</span>
</code></pre></div></div>
<p>(straight from <a href="https://claude.ai/">Claude AI</a>)</p>

<h2 id="summarizing-it-and-creating-tables">Summarizing it and creating tables</h2>

<p>Of course, you now also have  to properly capture all those results, store them, and be able to summarize them, and create tables from them. That’s another story.</p>
<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:functions">
      <p>See for instance <a href="https://medium.com/@josueparra2892/20-best-programming-practices-407df688b96e">https://medium.com/@josueparra2892/20-best-programming-practices-407df688b96e</a>, but this will be repeated many times. I was personally influenced by reading the (very accessible, but 900 pages!) “<a href="https://bookshop.org/p/books/code-complete-steve-mcconnell/12551815?ean=9780735619678">Code Complete</a>” by Steve McConnell. Desirable internal design characteristics include “minimal complexity” (KISS), “ease of maintenance”, and “reusability” <a href="#fnref:functions" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:proper-function">
      <p>In a proper function, you would pass the parameters as arguments, and validate that they are the right ones, etc.: <code class="language-plaintext highlighter-rouge">core-model(a,b,c)</code>. Read the programming language specific manual on how to properly write functions: <a href="https://www.stata.com/manuals/u17.pdf">Stata</a>, <a href="https://adv-r.hadley.nz/functions.html#functions">R via Hadley</a>, <a href="https://www.mathworks.com/help/matlab/ref/function.html">MATLAB</a>, etc. <a href="#fnref:proper-function" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>AEA Data Editor</name></author><category term="data editor tips" /><category term="replication packages" /><category term="code" /><category term="function libraries" /><summary type="html"><![CDATA[We often see researchers handle variants of their analysis by copying and pasting code, or by copying code files into separate directories, and making only minimal modifications. Some folks do this for robustness checks - same data, different analysis method, or a variant of the dependent variable - others for simulation of various scenarios - an economy without banks, an economy with credit-constrained banks, an economy with unconstrained banks. I won’t point to particular examples, to protect the (somewhat) innocent, but this is not a good idea.]]></summary></entry><entry><title type="html">On the use and redistribution of data</title><link href="https://aeadataeditor.github.io/posts/2024-04-29-use-and-reuse-of-data" rel="alternate" type="text/html" title="On the use and redistribution of data" /><published>2024-04-29T00:00:00-04:00</published><updated>2024-04-29T00:00:00-04:00</updated><id>https://aeadataeditor.github.io/posts/use-and-reuse-of-data</id><content type="html" xml:base="https://aeadataeditor.github.io/posts/2024-04-29-use-and-reuse-of-data"><![CDATA[<p>Many researchers are confused by the difference between “use” and “(re-)distribution” of data. In a nutshell, just because you are able to freely use the data for your own research purposes does not give you the right to distribute the data to others. The devil is in the details.</p>

<!-- more -->

<h2 id="a-scenario">A scenario</h2>

<p>You are happily browsing along the internet, and find an fabulous dataset you think you can use for your awesome idea. Download, analyze, submit, publish, … all good. But then the pesky journal asks for a replication package. Easy, right? Wrap up the code, the data, upload, … all good? Maybe. Possibly not.</p>

<h2 id="the-problem">The problem</h2>

<p>Many data used by economists stems from other data sources. Most of these data sources are on the internet. Anybody can use data that’s on the internet and do with it what they want, right?</p>

<p>As the discussion surrounding copyright and artificial intelligence shows, the answer is complex.<sup id="fnref:nytai"><a href="#fn:nytai" class="footnote" rel="footnote" role="doc-noteref">1</a></sup><sup id="fnref:silverman"><a href="#fn:silverman" class="footnote" rel="footnote" role="doc-noteref">2</a></sup> There is a concept of “fair use” in US copyright law, and in particular, it has been used to allow for legal webscraping.<sup id="fnref:webscraping"><a href="#fn:webscraping" class="footnote" rel="footnote" role="doc-noteref">3</a></sup></p>

<p>But that applies primarily for “use”. If you want to publish the data you obtained from elsewhere, that is no longer necessarily considered (fair) “use”, it falls under “redistribution” or “publication”.</p>

<h2 id="the-solution">The solution</h2>

<p>In principle, the solution is for data providers to establish clear terms of use and licenses. And many do, especially in the commercial space. In general, you will find that “terms of use” restrict certains uses and rights, and “licenses” allow or grant certain uses and rights.</p>

<p>Historically, it was software that was licensed, and “open source” licenses have a long history. Many such licenses are listed at the “<a href="https://opensource.org/licenses">open source initiative</a>”.</p>

<p>For data, a popular set of licenses are the “<a href="https://creativecommons.org/licenses/">Creative Commons</a>” licenses. These licenses are designed to be easy to understand and to use, and allow for a wide range of uses - including <strong>redistribution</strong>. The CC-BY license is abundantly clear about what it allows:</p>

<blockquote>
  <p><a href="https://creativecommons.org/licenses/by/4.0/">CC By 4.0 DEED</a>:</p>

  <p>You are free to:</p>

  <ul>
    <li>Share — copy and redistribute the material in any medium or format for any purpose, even commercially. 
[…]</li>
  </ul>

</blockquote>

<p>Other data licenses exist that allow for redistribution explicitly:</p>

<ul>
  <li><a href="https://opendatacommons.org/licenses/odbl/">Open Data Commons Open Database License (ODbL)</a></li>
  <li>various government “open data” licenses, such as the <a href="https://www.nationalarchives.gov.uk/doc/open-government-licence/version/3/">UK Open Government License</a> and Statistics Canada’s <a href="https://www.statcan.gc.ca/en/reference/licence">Statistics Canada Open Licence</a>.</li>
</ul>

<p>(often times, the differences are minor between these licenses).</p>

<h2 id="the-problem-part-2">The problem, part 2</h2>

<p>The problem is that many (academic) data providers still do not show or apply these licenses, and have no terms of use, or ones that are hidden. It thus becomes difficult for researchers to know what they can and cannot do with the data they find, leading to avoidable confusion.</p>

<p>Sometimes, these are identified at the time of downloading the data. For instance, the widely-used <a href="https://www.worldvaluessurvey.org/WVSDocumentationWV6.jsp">World Values Survey</a> displays four conditions to researchers who (after registering) download the data:</p>

<p><img src="/images/wvs-download-screenshot-20240429.png" alt="WVS download conditions" /></p>

<p>It otherwise mentions the “non-redistribution license” or that “data redistribution is prohibited” in multiple places, but there is no single “Terms of Use” page, or a “WVS License” page that is easily accessible and referenceable.</p>

<p>Even when terms of use are provided, permissions and restrictions are not necessarily linked together. For instance, the fabulous <a href="https://dhsprogram.com/">DHS Program</a> states on many of its pages</p>

<blockquote>
  <p>The DHS Program is authorized to distribute, at no cost, unrestricted survey data files for legitimate academic research.</p>
</blockquote>

<p>but one has to search for the <a href="https://dhsprogram.com/data/Terms-of-Use.cfm">Terms of Use</a>, tucked in between “Contraceptive Calendar Tutorial” and “DHS Github Code Share”, which state (also very clearly)</p>

<blockquote>
  <p>Conditions of Use for The DHS Program datasets 
(applies to all datasets downloaded from The DHS Program website: www.dhsprogram.com)</p>

  <p>[…]</p>
  <ul>
    <li>Agree that the datasets <strong>will not be shared</strong> with other researchers without the written consent of The DHS Program.</li>
  </ul>
</blockquote>

<p>(emphasis added). Many researchers include DHS data in their replication packages, and active data editors like myself have to remind them to remove the data from the replication package.</p>

<h2 id="the-takeaways">The takeaways</h2>

<h3 id="data-providers">Data providers</h3>

<ul>
  <li>Data providers should have a clear “Terms of Use” page, or a “License” page, that is easily accessible and referenceable.</li>
  <li>They should also include the license and conditions in every download.</li>
  <li>When data formats that allow for annotation (Stata, SAS), embed the license information in the dataset itself.</li>
</ul>

<h3 id="researchers">Researchers</h3>

<ul>
  <li>Always record the terms of use and license when you download the data.</li>
  <li>Search for “terms of use” or “license” on data providers’ websites.</li>
  <li>If the website asks for registration, it is highly likely that there are redistribution restrictions.</li>
  <li>Request that data providers make their terms of use and licenses more visible and accessible.</li>
  <li>Consult (and update) the <a href="https://social-science-data-editors.github.io/reference/TermsOfUse.html">Social Science Data Editors’ Terms of Use database</a>.</li>
</ul>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:nytai">
      <p>New York Times has sued OpenAI and Microsoft for having used their texts, see <a href="https://www.washingtonpost.com/technology/2024/01/04/nyt-ai-copyright-lawsuit-fair-use/">https://www.washingtonpost.com/technology/2024/01/04/nyt-ai-copyright-lawsuit-fair-use/</a>. <a href="#fnref:nytai" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:silverman">
      <p>Sarah Silverman and other authors have sued OpenAI over the use of their texts, but parts of that lawsuit have been dismissed, see <a href="https://www.reuters.com/legal/litigation/openai-gets-partial-win-authors-us-copyright-lawsuit-2024-02-13/">https://www.reuters.com/legal/litigation/openai-gets-partial-win-authors-us-copyright-lawsuit-2024-02-13/</a>. <a href="#fnref:silverman" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:webscraping">
      <p>See <a href="https://techcrunch.com/2022/04/18/web-scraping-legal-court/">https://techcrunch.com/2022/04/18/web-scraping-legal-court/</a>. <a href="#fnref:webscraping" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>AEA Data Editor</name></author><category term="data editor tips" /><category term="replication packages" /><category term="terms of use" /><category term="licenses" /><summary type="html"><![CDATA[Many researchers are confused by the difference between “use” and “(re-)distribution” of data. In a nutshell, just because you are able to freely use the data for your own research purposes does not give you the right to distribute the data to others. The devil is in the details.]]></summary></entry></feed>